Skip to navigation

Bridge Server Architecture & Session Management

View as Markdown

Build a server that sits between MeetStream and your AI stack. The bridge receives real-time meeting audio, manages one session per MeetStream connection, routes audio through your processing pipeline, and sends responses (audio, chat, images) back into the meeting.


Architecture
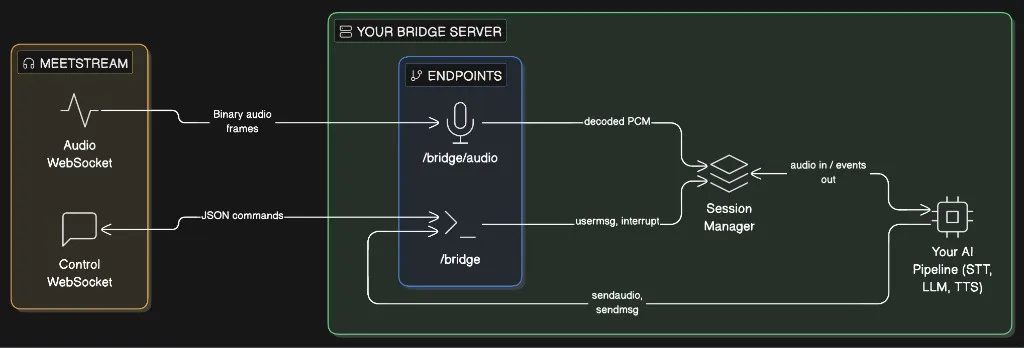
MeetStream Bridge Architecture

The bridge server exposes two WebSocket endpoints. Each MeetStream connection opens one to each:

EndpointDirectionFormatPurpose
/bridge/audioMeetStream → YouBinary framesLive meeting audio with speaker metadata
/bridgeMeetStream ↔ YouJSON textCommands: send audio, chat, images, interrupt

Each MeetStream connection is identified by a bot_id. The session manager maintains one AI session per bot_id, created on first connection and torn down when both WebSockets disconnect.


Session Lifecycle
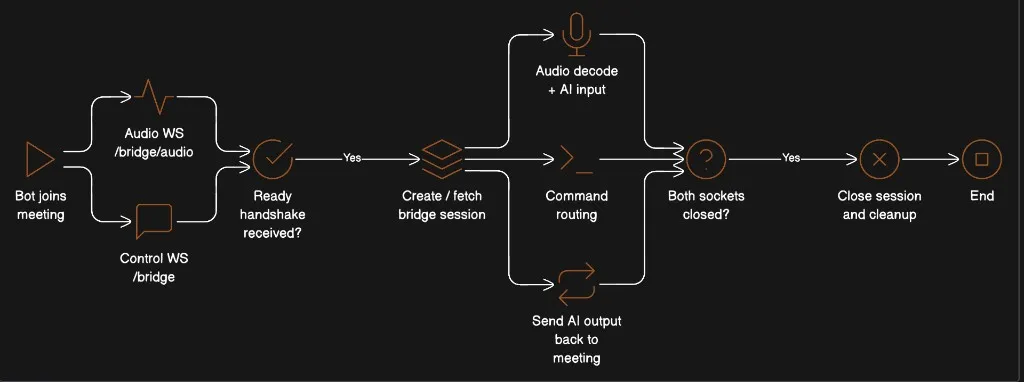
MeetStream Bridge Session Lifecycle

Key rules:

  • Either channel can arrive first. The session is created on whichever connects first.
  • Both channels share the same bot_id and the same AI session.
  • Cleanup happens when both WebSockets have disconnected for a given bot_id.

Core Components

1. Session Manager

The session manager is the central coordinator. It maps bot_id to:

  • An AI session (your STT/LLM/TTS pipeline)
  • References to the audio and control WebSockets
  • Per-session locks to prevent race conditions during creation
import asyncio
import json
import logging
from typing import Any, Dict, Optional
from fastapi import WebSocket
from starlette.websockets import WebSocketState
logger = logging.getLogger("bridge")
class SessionManager:
def __init__(self):
self.sessions: Dict[str, Any] = {}
self.audio_ws: Dict[str, WebSocket] = {}
self.control_ws: Dict[str, WebSocket] = {}
self._locks: Dict[str, asyncio.Lock] = {}
def _lock_for(self, bot_id: str) -> asyncio.Lock:
if bot_id not in self._locks:
self._locks[bot_id] = asyncio.Lock()
return self._locks[bot_id]
async def ensure_session(self, bot_id: str):
"""Create an AI session for this bot_id if one doesn't exist."""
async with self._lock_for(bot_id):
if bot_id in self.sessions:
return
session = await self._create_session(bot_id)
self.sessions[bot_id] = session
logger.info(f"[{bot_id}] Session created")
async def close_session(self, bot_id: str):
"""Tear down the AI session for this bot_id."""
async with self._lock_for(bot_id):
session = self.sessions.pop(bot_id, None)
if session:
await self._destroy_session(bot_id, session)
logger.info(f"[{bot_id}] Session closed")
async def maybe_cleanup(self, bot_id: str):
"""Close the session if both WebSockets have disconnected."""
if bot_id not in self.audio_ws and bot_id not in self.control_ws:
await self.close_session(bot_id)
async def _create_session(self, bot_id: str) -> Any:
"""
Replace this with your AI pipeline initialization.
Examples: start an STT stream, create an LLM session,
initialize a TTS engine, connect to a realtime API, etc.
"""
raise NotImplementedError("Implement _create_session()")
async def _destroy_session(self, bot_id: str, session: Any):
"""
Replace this with your AI pipeline teardown.
Close connections, flush buffers, release resources.
"""
raise NotImplementedError("Implement _destroy_session()")

2. Audio Decoder

Decodes the binary frame format from MeetStream. See Live Audio Capture & Frame Decoding for the full specification.

from typing import Optional, Tuple
def decode_audio_frame(data: bytes) -> Optional[Tuple[str, str, bytes]]:
"""Decode a MeetStream binary audio frame.
Returns (speaker_id, speaker_name, pcm_bytes) or None.
"""
if len(data) < 5 or data[0] != 0x01:
return None
sid_len = int.from_bytes(data[1:3], "little")
speaker_id = data[3 : 3 + sid_len].decode("utf-8")
off = 3 + sid_len
sname_len = int.from_bytes(data[off : off + 2], "little")
off += 2
speaker_name = data[off : off + sname_len].decode("utf-8")
off += sname_len
return speaker_id, speaker_name, data[off:]

3. Audio Resampler

Meeting audio arrives at 48 kHz. Most AI models expect a different rate (e.g., 24 kHz for OpenAI Realtime, 16 kHz for Whisper). Resample before feeding your pipeline, and resample back to 48 kHz before sending to the meeting.

import numpy as np
def resample_pcm16(pcm_bytes: bytes, src_hz: int, dst_hz: int) -> bytes:
"""Resample PCM16 LE audio between sample rates."""
if src_hz == dst_hz:
return pcm_bytes
x = np.frombuffer(pcm_bytes, dtype=np.int16).astype(np.float32)
n_out = int(len(x) * dst_hz / src_hz)
t_src = np.linspace(0, 1, len(x), endpoint=False)
t_dst = np.linspace(0, 1, n_out, endpoint=False)
y = np.interp(t_dst, t_src, x)
return np.clip(y, -32768, 32767).astype(np.int16).tobytes()
INCOMING_RATE = 48000 # MeetStream sends 48kHz
MODEL_RATE = 24000 # Your model's expected rate
OUTGOING_RATE = 48000 # MeetStream expects 48kHz back

4. Speaker Filter

Filter out MeetStream’s own audio to prevent echo/feedback loops. The display name appears in the speaker_name field.

IGNORED_SPEAKERS = {
"My Bot Name",
"Meeting Assistant",
}
AGENT_KEYWORDS = ["bot", "agent", "assistant", "ai"]
def should_ignore_speaker(speaker_name: str) -> bool:
if speaker_name in IGNORED_SPEAKERS:
return True
lower = speaker_name.lower()
return any(kw in lower for kw in AGENT_KEYWORDS)

5. Command Sender

Helper functions to build outbound commands for the control channel. See Meeting Control & Command Patterns for the full command reference.

import base64
async def safe_send(ws: WebSocket, payload: dict):
"""Send JSON to a WebSocket, swallowing errors."""
try:
if ws.client_state == WebSocketState.CONNECTED:
await ws.send_text(json.dumps(payload))
except Exception as e:
logger.warning(f"WebSocket send failed: {e}")
async def send_audio_to_meeting(ws: WebSocket, bot_id: str, pcm_bytes: bytes, sample_rate: int = 48000):
await safe_send(ws, {
"command": "sendaudio",
"bot_id": bot_id,
"audiochunk": base64.b64encode(pcm_bytes).decode("utf-8"),
"sample_rate": sample_rate,
"encoding": "pcm16",
"channels": 1,
"endianness": "little",
})
async def send_chat_to_meeting(ws: WebSocket, bot_id: str, text: str):
await safe_send(ws, {
"command": "sendmsg",
"bot_id": bot_id,
"message": text,
"msg": text,
})
async def send_interrupt_to_meeting(ws: WebSocket, bot_id: str):
await safe_send(ws, {
"command": "interrupt",
"bot_id": bot_id,
"action": "clear_audio_queue",
})

WebSocket Endpoints

Audio Endpoint: /bridge/audio

Receives binary audio frames from the meeting. Decodes speaker metadata, filters out MeetStream’s own audio, and routes PCM to your AI pipeline.

from fastapi import FastAPI, WebSocket, WebSocketDisconnect
app = FastAPI()
manager = SessionManager()
@app.websocket("/bridge/audio")
async def audio_endpoint(websocket: WebSocket):
await websocket.accept()
bot_id = None
try:
while True:
raw = await websocket.receive()
# Text frames: handshake or legacy JSON audio
if "text" in raw and raw["text"]:
data = json.loads(raw["text"])
# Handshake
if data.get("type") == "ready":
bot_id = data.get("bot_id")
if not bot_id:
await websocket.close(code=1003)
return
manager.audio_ws[bot_id] = websocket
await manager.ensure_session(bot_id)
await safe_send(websocket, {
"type": "ack",
"message": f"Audio channel bound to {bot_id}",
})
continue
# Legacy JSON audio (for backward compatibility)
if data.get("type") == "PCMChunk" and bot_id:
speaker = data.get("speakerName", "")
if should_ignore_speaker(speaker):
continue
audio_b64 = data.get("audioData")
if audio_b64:
pcm = base64.b64decode(audio_b64)
pcm_resampled = resample_pcm16(pcm, INCOMING_RATE, MODEL_RATE)
session = manager.sessions.get(bot_id)
if session:
await session.send_audio(pcm_resampled)
continue
# Binary frames: current binary audio protocol
if "bytes" in raw and raw["bytes"] and bot_id:
result = decode_audio_frame(raw["bytes"])
if result is None:
continue
speaker_id, speaker_name, pcm_bytes = result
if should_ignore_speaker(speaker_name):
continue
if pcm_bytes:
pcm_resampled = resample_pcm16(pcm_bytes, INCOMING_RATE, MODEL_RATE)
session = manager.sessions.get(bot_id)
if session:
await session.send_audio(pcm_resampled)
except WebSocketDisconnect:
pass
except Exception as e:
logger.error(f"[{bot_id}] Audio endpoint error: {e}")
finally:
if bot_id:
manager.audio_ws.pop(bot_id, None)
await manager.maybe_cleanup(bot_id)

Control Endpoint: /bridge

Receives the MeetStream handshake and inbound commands (usermsg, interrupt). Your AI pipeline sends outbound commands (sendaudio, sendmsg, sendchat, interrupt) over this same connection.

@app.websocket("/bridge")
async def control_endpoint(websocket: WebSocket):
await websocket.accept()
bot_id = None
try:
# Wait for handshake
init = json.loads(await websocket.receive_text())
if init.get("type") != "ready" or not init.get("bot_id"):
await websocket.close(code=1003)
return
bot_id = init["bot_id"]
manager.control_ws[bot_id] = websocket
await manager.ensure_session(bot_id)
await safe_send(websocket, {
"command": "ack",
"bot_id": bot_id,
"message": f"Control channel bound to {bot_id}",
})
# Start the event pump that forwards AI output to MeetStream
asyncio.create_task(event_pump(bot_id))
# Main loop: receive inbound commands from MeetStream
while True:
data = json.loads(await websocket.receive_text())
command = data.get("command")
if command == "usermsg":
text = data.get("message", "")
if text:
session = manager.sessions.get(bot_id)
if session:
await session.send_text(text)
elif command == "interrupt":
session = manager.sessions.get(bot_id)
if session and hasattr(session, "interrupt"):
await session.interrupt()
except WebSocketDisconnect:
pass
except Exception as e:
logger.error(f"[{bot_id}] Control endpoint error: {e}")
finally:
if bot_id:
manager.control_ws.pop(bot_id, None)
await manager.maybe_cleanup(bot_id)

Event Pump

The event pump is a background task that continuously reads output from your AI pipeline and forwards it to the meeting through the control WebSocket. This is the outbound half of the bridge.

async def event_pump(bot_id: str):
"""Forward AI pipeline output to the MeetStream control channel."""
session = manager.sessions.get(bot_id)
if not session:
return
try:
async for event in session:
ws = manager.control_ws.get(bot_id)
if not ws or ws.client_state != WebSocketState.CONNECTED:
continue
# AI produced audio → send to meeting
if event.type == "audio":
pcm_model = event.audio_bytes # at MODEL_RATE
pcm_out = resample_pcm16(pcm_model, MODEL_RATE, OUTGOING_RATE)
await send_audio_to_meeting(ws, bot_id, pcm_out, OUTGOING_RATE)
# AI speech was interrupted → clear the playback queue
elif event.type == "audio_interrupted":
await send_interrupt_to_meeting(ws, bot_id)
# AI produced a text response → send as chat
elif event.type == "text_response":
await send_chat_to_meeting(ws, bot_id, event.text)
except Exception as e:
logger.error(f"[{bot_id}] Event pump error: {e}")

Note: The event types above (audio, audio_interrupted, text_response) are illustrative. Replace them with whatever events your AI framework emits.


Full Working Skeleton

A minimal but complete bridge server. Replace the YourAISession class with your actual AI pipeline.

import asyncio
import base64
import json
import logging
from contextlib import asynccontextmanager
from typing import Any, Dict, Optional, Tuple
import numpy as np
from fastapi import FastAPI, WebSocket, WebSocketDisconnect
from starlette.websockets import WebSocketState
logging.basicConfig(level=logging.INFO)
logger = logging.getLogger("bridge")
# ── Configuration ─────────────────────────────────────────────────────────────
INCOMING_RATE = 48000 # MeetStream sends 48kHz
MODEL_RATE = 24000 # Your AI model's expected sample rate
OUTGOING_RATE = 48000 # MeetStream expects 48kHz back
IGNORED_SPEAKERS = {"My Bot Name"}
AGENT_KEYWORDS = ["bot", "agent", "assistant"]
# ── Audio utilities ───────────────────────────────────────────────────────────
def decode_audio_frame(data: bytes) -> Optional[Tuple[str, str, bytes]]:
if len(data) < 5 or data[0] != 0x01:
return None
sid_len = int.from_bytes(data[1:3], "little")
sid = data[3 : 3 + sid_len].decode("utf-8")
off = 3 + sid_len
sname_len = int.from_bytes(data[off : off + 2], "little")
off += 2
sname = data[off : off + sname_len].decode("utf-8")
off += sname_len
return sid, sname, data[off:]
def resample_pcm16(pcm_bytes: bytes, src_hz: int, dst_hz: int) -> bytes:
if src_hz == dst_hz:
return pcm_bytes
x = np.frombuffer(pcm_bytes, dtype=np.int16).astype(np.float32)
n_out = int(len(x) * dst_hz / src_hz)
t_src = np.linspace(0, 1, len(x), endpoint=False)
t_dst = np.linspace(0, 1, n_out, endpoint=False)
y = np.interp(t_dst, t_src, x)
return np.clip(y, -32768, 32767).astype(np.int16).tobytes()
def should_ignore_speaker(name: str) -> bool:
if name in IGNORED_SPEAKERS:
return True
lower = name.lower()
return any(kw in lower for kw in AGENT_KEYWORDS)
# ── Safe WebSocket send ───────────────────────────────────────────────────────
async def safe_send(ws: WebSocket, payload: dict):
try:
if ws.client_state == WebSocketState.CONNECTED:
await ws.send_text(json.dumps(payload))
except Exception as e:
logger.warning(f"send failed: {e}")
# ── Your AI session (replace this) ───────────────────────────────────────────
class YourAISession:
"""
Stub. Replace with your actual AI pipeline.
This could be:
- An OpenAI Realtime API session
- A Whisper STT + GPT + TTS pipeline
- A LiveKit agent session
- Any other audio-in/audio-out system
"""
async def send_audio(self, pcm_bytes: bytes):
"""Feed PCM audio into your pipeline."""
pass
async def send_text(self, text: str):
"""Feed user text into your pipeline."""
pass
async def interrupt(self):
"""Signal the pipeline to stop generating."""
pass
async def events(self):
"""Yield output events from your pipeline.
Expected event shapes (adapt to your framework):
{"type": "audio", "pcm_bytes": bytes}
{"type": "audio_interrupted"}
{"type": "text", "content": str}
"""
while True:
await asyncio.sleep(1) # replace with actual event stream
return
# ── Session Manager ───────────────────────────────────────────────────────────
class SessionManager:
def __init__(self):
self.sessions: Dict[str, YourAISession] = {}
self.audio_ws: Dict[str, WebSocket] = {}
self.control_ws: Dict[str, WebSocket] = {}
self._locks: Dict[str, asyncio.Lock] = {}
def _lock(self, bot_id: str) -> asyncio.Lock:
if bot_id not in self._locks:
self._locks[bot_id] = asyncio.Lock()
return self._locks[bot_id]
async def ensure_session(self, bot_id: str):
async with self._lock(bot_id):
if bot_id in self.sessions:
return
self.sessions[bot_id] = YourAISession()
asyncio.create_task(self._event_pump(bot_id))
logger.info(f"[{bot_id}] Session created")
async def close_session(self, bot_id: str):
async with self._lock(bot_id):
self.sessions.pop(bot_id, None)
logger.info(f"[{bot_id}] Session closed")
async def maybe_cleanup(self, bot_id: str):
if bot_id not in self.audio_ws and bot_id not in self.control_ws:
await self.close_session(bot_id)
async def _event_pump(self, bot_id: str):
"""Background task: forward AI output → MeetStream control WS."""
session = self.sessions.get(bot_id)
if not session:
return
try:
async for event in session.events():
ws = self.control_ws.get(bot_id)
if not ws or ws.client_state != WebSocketState.CONNECTED:
continue
etype = event.get("type")
if etype == "audio":
pcm_out = resample_pcm16(event["pcm_bytes"], MODEL_RATE, OUTGOING_RATE)
await safe_send(ws, {
"command": "sendaudio",
"bot_id": bot_id,
"audiochunk": base64.b64encode(pcm_out).decode("utf-8"),
"sample_rate": OUTGOING_RATE,
"encoding": "pcm16",
"channels": 1,
"endianness": "little",
})
elif etype == "audio_interrupted":
await safe_send(ws, {
"command": "interrupt",
"bot_id": bot_id,
"action": "clear_audio_queue",
})
elif etype == "text":
await safe_send(ws, {
"command": "sendmsg",
"bot_id": bot_id,
"message": event["content"],
"msg": event["content"],
})
except Exception as e:
logger.error(f"[{bot_id}] Event pump error: {e}")
manager = SessionManager()
# ── FastAPI Application ───────────────────────────────────────────────────────
@asynccontextmanager
async def lifespan(app: FastAPI):
yield
app = FastAPI(title="MeetStream Bridge", lifespan=lifespan)
@app.get("/health")
async def health():
return {"status": "healthy"}
@app.websocket("/bridge/audio")
async def audio_endpoint(websocket: WebSocket):
"""Receives live meeting audio from MeetStream."""
await websocket.accept()
bot_id = None
try:
while True:
raw = await websocket.receive()
# Text frame: handshake or legacy JSON
if "text" in raw and raw["text"]:
data = json.loads(raw["text"])
if data.get("type") == "ready":
bot_id = data.get("bot_id")
if not bot_id:
await websocket.close(code=1003)
return
manager.audio_ws[bot_id] = websocket
await manager.ensure_session(bot_id)
await safe_send(websocket, {
"type": "ack",
"message": f"Audio channel bound to {bot_id}",
})
elif data.get("type") == "PCMChunk" and bot_id:
speaker = data.get("speakerName", "")
if should_ignore_speaker(speaker):
continue
b64 = data.get("audioData")
if b64:
pcm = base64.b64decode(b64)
pcm_r = resample_pcm16(pcm, INCOMING_RATE, MODEL_RATE)
session = manager.sessions.get(bot_id)
if session:
await session.send_audio(pcm_r)
continue
# Binary frame: current protocol
if "bytes" in raw and raw["bytes"] and bot_id:
result = decode_audio_frame(raw["bytes"])
if result is None:
continue
_, speaker_name, pcm_bytes = result
if should_ignore_speaker(speaker_name):
continue
if pcm_bytes:
pcm_r = resample_pcm16(pcm_bytes, INCOMING_RATE, MODEL_RATE)
session = manager.sessions.get(bot_id)
if session:
await session.send_audio(pcm_r)
except WebSocketDisconnect:
pass
except Exception as e:
logger.error(f"[{bot_id}] Audio error: {e}")
finally:
if bot_id:
manager.audio_ws.pop(bot_id, None)
await manager.maybe_cleanup(bot_id)
@app.websocket("/bridge")
async def control_endpoint(websocket: WebSocket):
"""Two-way command channel with MeetStream."""
await websocket.accept()
bot_id = None
try:
init = json.loads(await websocket.receive_text())
if init.get("type") != "ready" or not init.get("bot_id"):
await websocket.close(code=1003)
return
bot_id = init["bot_id"]
manager.control_ws[bot_id] = websocket
await manager.ensure_session(bot_id)
await safe_send(websocket, {
"command": "ack",
"bot_id": bot_id,
"message": f"Control channel bound to {bot_id}",
})
while True:
data = json.loads(await websocket.receive_text())
command = data.get("command")
if command == "usermsg":
text = data.get("message", "")
if text:
session = manager.sessions.get(bot_id)
if session:
await session.send_text(text)
elif command == "interrupt":
session = manager.sessions.get(bot_id)
if session:
await session.interrupt()
except WebSocketDisconnect:
pass
except Exception as e:
logger.error(f"[{bot_id}] Control error: {e}")
finally:
if bot_id:
manager.control_ws.pop(bot_id, None)
await manager.maybe_cleanup(bot_id)
if __name__ == "__main__":
import uvicorn
uvicorn.run("server:app", host="0.0.0.0", port=8000, reload=True)

Run:

pip install fastapi uvicorn numpy
uvicorn server:app --host 0.0.0.0 --port 8000

Connecting MeetStream

When creating a MeetStream session, point both WebSocket URLs at your bridge server:

{
"meeting_link": "https://meet.google.com/abc-defg-hij",
"bot_name": "My Assistant",
"live_audio_required": {
"websocket_url": "wss://your-bridge.com/bridge/audio"
},
"socket_connection_url": {
"websocket_url": "wss://your-bridge.com/bridge"
}
}

Both connections carry the same bot_id in their handshake, so the session manager can link them together.


Design Decisions

Separation of concerns. The audio channel is high-throughput binary data (hundreds of frames per minute). The control channel is low-frequency JSON commands. Splitting them avoids head-of-line blocking and makes it easier to handle each independently.

Backward compatibility. Older MeetStream versions send audio as JSON PCMChunk messages with base64-encoded audio. Current versions send binary frames (significantly more efficient). The bridge should accept both.

Both WebSocket connections race to ensure_session(). Without a lock, two AI sessions could be created for the same bot_id. The async lock ensures exactly one session is created.

A single reconnecting WebSocket shouldn’t destroy the running session. The session stays alive as long as at least one channel is connected.

MeetStream captures audio at 48 kHz (the standard WebAudio and Zoom SDK rate). Your model may need 16 kHz or 24 kHz. On the return path, MeetStream’s virtual speaker operates at 48 kHz. The bridge handles both conversions so neither MeetStream nor your model needs to know about the other’s sample rate.